Work/Dropship.ai

A search platform over 614 million products.

Dropship.ai sold subscriptions to online sellers who want to know which products are getting traction before they stock them. Shapelab designed the data pipeline and built the application from nothing, then kept it running for almost four years.
Client
Product-research SaaS for e-commerce sellers
Location
Milan, Italy
Years
2019 to 2022
Our role
Designed and built the whole product, then ran it
614Mproducts searchable
60Mproducts re-checked every day
4years, almost, built and run by one team
0lines of code when we started
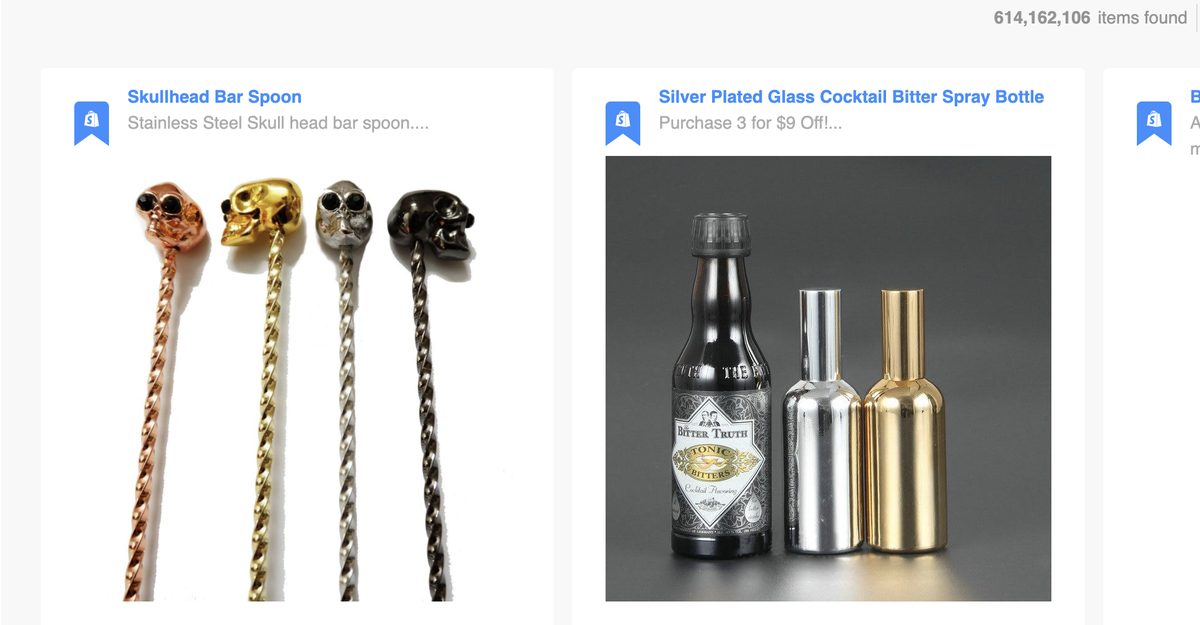
Dropship.ai product search with a counter of 614,162,106 items found

Product search in the running application · 614,162,106 items found

The problem

Coverage, freshness and speed, all at once.

The product is only worth paying for if three things hold together. None of the source data arrives through one clean feed: catalogue data comes from each store separately, engagement from social networks with strict rate limits, and media from posts that can vanish. The engineering job was to keep all of it moving, every day, on a budget a start-up could pay.

  • 01Coverage. A seller wants every store, not a sample. That means hundreds of millions of products.
  • 02Freshness. Engagement numbers change daily. A share count from last month is useless for spotting a trend.
  • 03Speed. Search across the whole catalogue has to answer in seconds, with free text, negative keywords and range filters.
What we built

A pipeline that never stops.

01

Every store, not a sample

  • The platform reads the catalogues of online stores continuously
  • Whatever has gone longest without a refresh is always next in line
02

Fresh numbers every day

  • About 60 million products are re-checked daily for how much attention they are getting
  • Sellers see what is taking off this week, not last month
03

Search that answers in seconds

  • Free text, exclusions, price, date and popularity filters across the whole catalogue
  • Heavy background updates never slow a subscriber’s search
04

Nothing disappears

  • Product images and videos are kept, so a result still shows after the original is deleted
  • Full-page snapshots on request
05

A subscription business around it

  • Trial, three paid plans and team accounts
  • Saved searches, bookmarks and exports
06

Run by non-developers

  • A status screen shows every background process
  • Staff can see and restart them without calling an engineer
How it flows

From a store's catalogue to a search result.

01
StoresCatalogues read one by one
02
QueueRefilled every minute, oldest first
03
CatalogueNew, changed and removed products
04
Daily re-check60 million products
05
SearchAnswers in the subscriber’s browser
The outcome

What it changed.

  • 01614 million products searchable. The catalogue grew from 366 million in July 2020.
  • 02From nothing to a running business. One team took it from an empty project to a subscription product and kept it running for almost four years.
  • 03Around the clock. The pipeline fed itself day and night without manual work.
Data platform in mind?

Need a pipeline that
keeps up?

If your product lives on large volumes of data, queues and search, tell us what it has to do. You’ll get a reply within 1 business day.

170+ projects · 100+ clients · 17+ years